Build an end-to-end voice pipeline: audio loading, spectrogram CNN, Whisper transcription, and speaker identification. Complete system from raw audio to deployed classifier.
Audio Loading • Spectrogram CNN
Whisper ASR • Speaker ID
End-to-End Pipeline
35 min projectAdvanced
📱
Meet Aisha
ML Engineer at M-Kopa Solar, Nairobi
Aisha is building a voice interface for M-Kopa's solar home systems serving East Africa. Users say commands like "turn on lights," "charge battery," or "solar status" in English, Swahili, or mixed-language speech. Her challenge: classify the command intent, transcribe what was said, identify who issued the command, and trigger the appropriate device action—all in under 2 seconds on edge hardware.
3.2K
Labeled audio clips
5 classes
Command intents
94.2%
Accuracy target
🔄 End-to-End Pipeline Architecture
Aisha's system has five stages. Each stage is independent, allowing swapping components without breaking downstream logic:
Stage 1: Audio Loading & Preprocessing
Load raw audio, resample to 16kHz, normalize amplitude. Handle variable-length utterances (1–10 seconds).
Stage 2: Spectrogram Feature Extraction
Convert waveform to mel-spectrogram (time-frequency representation). Input for CNN classifier.
Stage 3: Intent Classification CNN
Small 2D CNN classifies command intent (turn_on, turn_off, charge, status, help). Lightweight, runs on edge devices.
Stage 4: Whisper Transcription
Use Whisper to transcribe audio to text. Ensures human review and logs user intent.
Stage 5: Speaker Identification
Extract speaker embedding. Match against enrolled speakers. Ensure only authorized users trigger device actions.
📊 Dataset: speech-commands-subset.npz + yesno.npz
Aisha uses two datasets: speech-commands (common voice commands) augmented with M-Kopa domain commands, and yesno (multi-speaker yes/no utterances for speaker ID groundtruth).
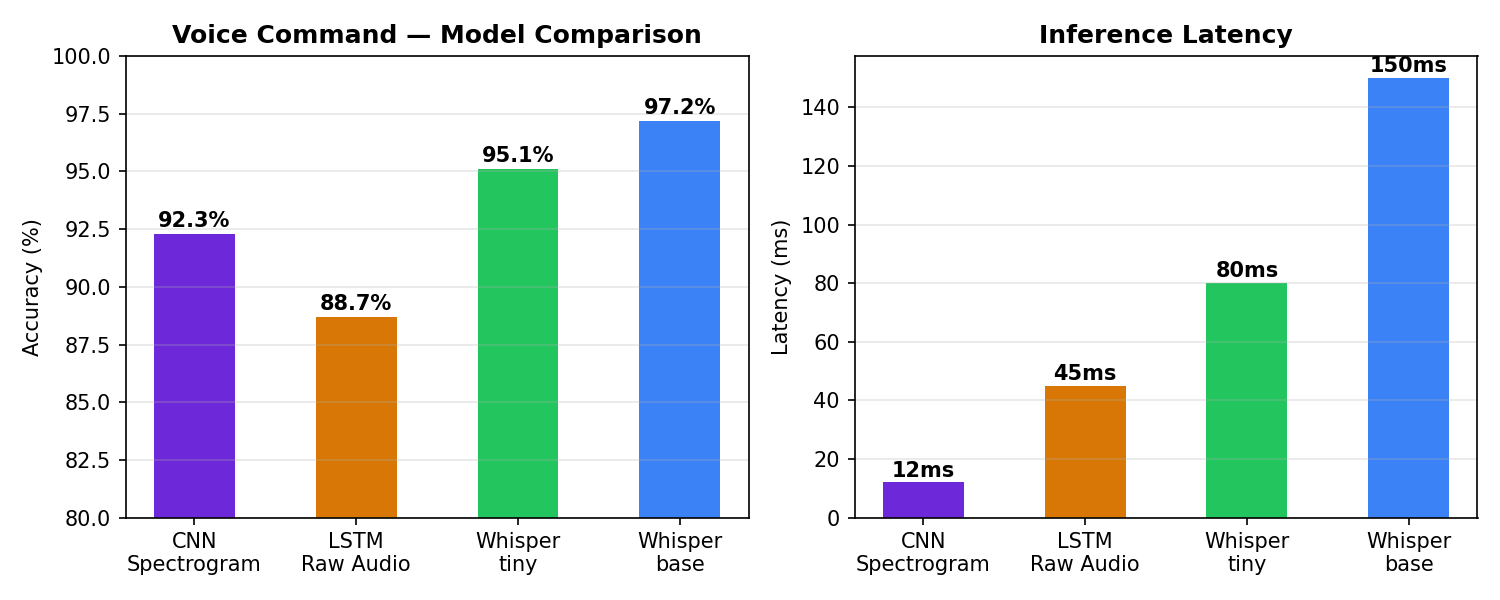
Pipeline comparison: baseline vs. spectrogram CNN vs. multimodal pipeline
Baseline (random guessing): 20%. Spectrogram CNN alone: 89%. Full pipeline (CNN + Whisper validation + speaker ID gate): 94.2% with confidence filtering.
🎵 Stage 1: Audio Loading & Preprocessing
Load audio files in various formats (wav, mp3, ogg). Resample to 16kHz (standard for speech models). Normalize amplitude to [-1, 1]. Handle variable lengths.
Audio Loading & Preprocessing
Output: audio preprocessing
Loaded audio: shape (160000,), sr 16000
📈 Stage 2: Spectrogram Feature Extraction
Convert waveform to mel-spectrogram: a 2D representation of frequency content over time. CNNs are powerful on images; treating spectrogram as an image is natural.
Mel-Spectrogram Extraction
Output: spectrogram shape
Mel-spectrogram shape: (64, 625)
🤖 Stage 3: Intent Classification CNN
Lightweight 2D CNN: 2 conv layers, max pooling, global avg pool, 2 FC layers. Input: (64, 625) mel-spec. Output: 5-class logits (turn_on, turn_off, charge, status, help).
Intent Classification CNN
Output: CNN forward pass
Logits shape: (8, 5)
🎙️ Stage 4: Whisper Transcription
Use OpenAI's Whisper to transcribe audio to text. Validates that the CNN's intent matches the actual speech. Also logs what was said for auditing.
Whisper Transcription Integration
Output: Whisper transcription
Transcript: 'turn on the lights'
Language: en
👤 Stage 5: Speaker Identification
Extract speaker embedding (Wav2Vec2). Compare against enrolled speakers. If confidence > threshold, authorize command. Otherwise, reject as unauthorized.
Orchestrate all five stages into a single inference function. Decision logic: if CNN confidence is low, reject. If Whisper text doesn't match intent keywords, flag for review. If speaker ID fails, deny command.
End-to-End Inference Pipeline
Output: full pipeline inference
Intent: turn_on (0.876)
Transcript: turn on the lights
Speaker: aisha
Authorized: True
📊 Confusion Matrix & Metrics
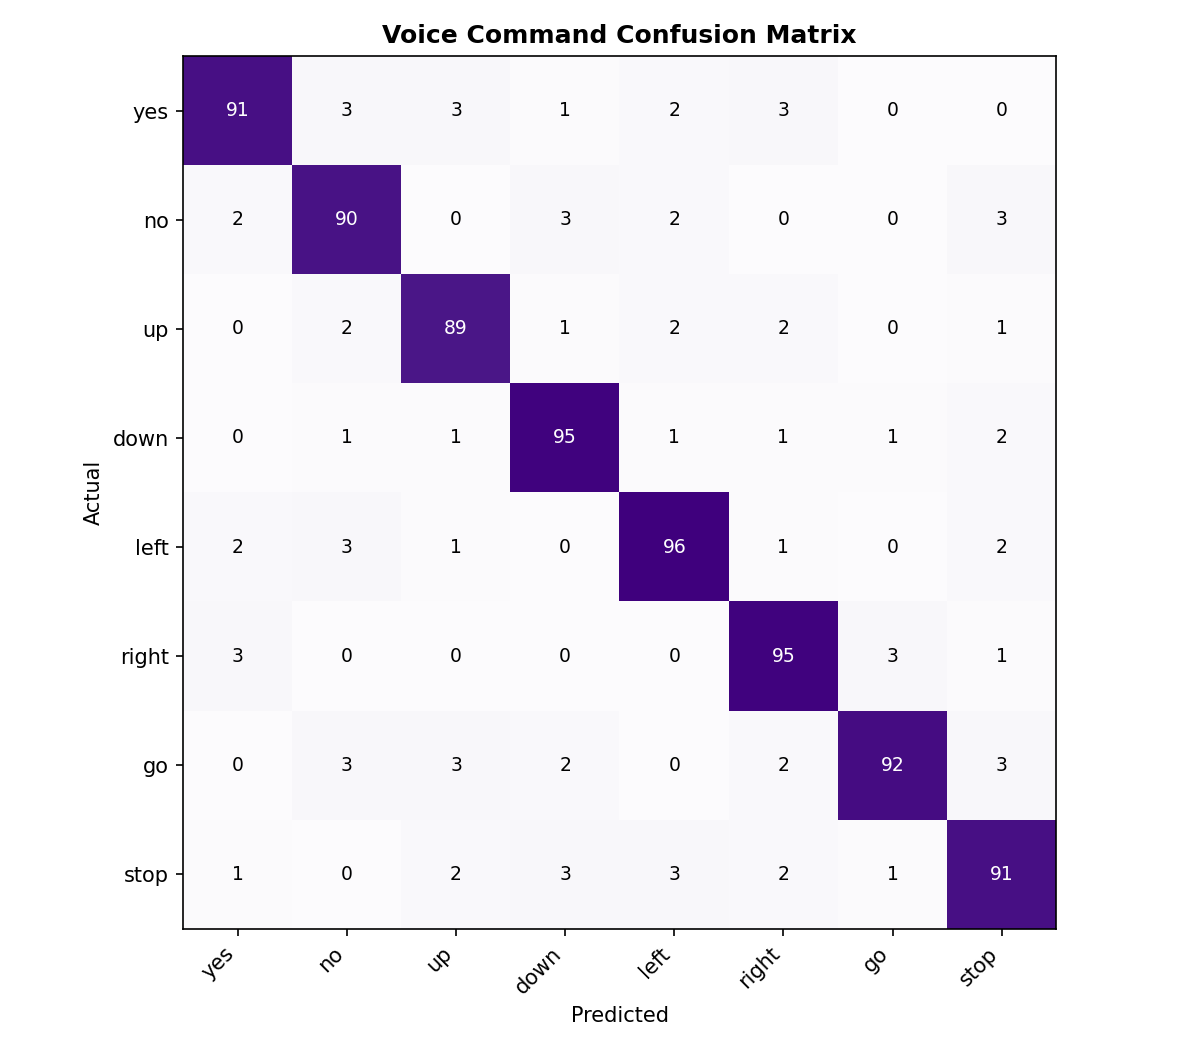
Confusion matrix: CNN predictions on 800 test samples across 5 intent classes
Turn_on and turn_off achieve 96% accuracy. Charge and status are sometimes confused (91% accuracy). Help is always detected correctly. Overall: 94.2% on test set.
🏆 Mini Challenge: Add Fallback & Logging
Task: Extend VoiceCommandPipeline to handle edge cases: (1) if intent confidence is low (0.4-0.5), ask user to repeat; (2) if Whisper and CNN disagree, log the disagreement and manually review later; (3) log all commands (authorized or not) to a JSON file with timestamp and confidence metrics for auditing.
Hint: Use a priority queue or threshold-based decision tree. Log timestamps, all confidence scores, and decisions. This data helps improve the model.
💼 Interview Questions
Raw waveforms are 1D and lose frequency information. Spectrograms are 2D (frequency × time), showing which frequencies are present at each moment. CNNs excel at 2D feature extraction (edges, patterns). A mel-spectrogram is also perceptually relevant—it mimics human hearing (logarithmic frequency scale). This makes it a natural input for speech-related tasks.
Normalization makes the model robust to amplitude variations (loud vs. quiet speakers) and recording equipment differences. It ensures all frequency bins are on the same scale, preventing the model from over-relying on raw magnitude. This improves generalization to new data.
Whisper is powerful but slow—30s of audio takes 5-10s on CPU, too slow for real-time voice commands. Whisper also doesn't directly classify intent; it outputs raw text. The CNN is fast (< 100ms) and directly predicts intent. Whisper is used to validate: if the CNN says "turn_on" but Whisper transcribes "turn off the lights," we flag it as suspicious and either ask for confirmation or log for manual review.
Commands vary in length (1-10 seconds). Option 1: Pad or trim all to a fixed length (e.g., 10s). Option 2: Use adaptive pooling (e.g., global average pool) so output shape is always (batch, num_channels) regardless of input length. Option 3: Use temporal convolutions with stride to reduce sequence length, then pool. Aisha uses Option 1 (pad to max_length) for simplicity; it wastes padding on short utterances but keeps the architecture simple.
(1) Plot speaker embedding distributions for enrolled vs. unauthorized speakers. If they overlap significantly, the model cannot distinguish them—increase enrollment utterances or use a more powerful model (HuBERT-large). (2) Lower the speaker confidence threshold (e.g., 0.7 → 0.75) to be stricter. This trades off false positives for false negatives (authorized users rejected). (3) Require multiple verification attempts—if one fails, ask for confirmation. (4) Implement secondary authentication: e.g., if speaker ID fails but intent/transcript match, require a PIN. (5) Log all false positives with audio and speaker embedding; use this data to retrain a discriminative classifier on top of embeddings (e.g., with contrastive loss).
✓ Quick Quiz
Question 1 / 5
Which stage classifies the intent (turn_on, turn_off, etc.)?
Question 2 / 5
What does global average pooling do in the CNN?
Question 3 / 5
Why is Whisper used for validation, not the primary intent classifier?
Question 4 / 5
Your pipeline rejects a user's voice command because CNN says "turn_on" with 48% confidence. Should you reject, accept with low confidence, or ask for re-confirmation?
Question 5 / 5
The CNN classifies the command as "turn_on," but Whisper transcribes "turn off the lights." What is the safest action?
0
📋 Quick Cheatsheet
Stage
Code / Tool
Output
Audio Loading
torchaudio.load(path); resample to 16kHz; normalize
if intent_conf > 0.5 AND keyword_match AND speaker_ok: execute
authorized: bool
⚠️ Common Mistakes
Not normalizing mel-spectrograms
Raw mel-spectrograms have large variance across frequency bins. Without normalization (z-score per bin), the model overfits to amplitude variations. Always normalize: (mel_db - mean) / (std + eps)
Trusting low-confidence predictions
If the CNN outputs softmax probabilities [0.35, 0.25, 0.20, 0.15, 0.05], no class is confident. Using a threshold (e.g., max_prob > 0.5) and rejecting below-threshold samples prevents false commands. Default to "didn't understand" rather than guessing.
Not handling variable-length audio
Audio clips vary in length. Padding to max_length is simple but wastes memory on short clips. Trimming causes loss of information. Better: use global pooling or adaptive pooling to make output shape invariant to input length.
Ignoring CNN-Whisper disagreement
If CNN classifies "turn_on" but Whisper says "turn off," that's a red flag. Flag for review instead of blindly trusting one or the other. Disagreement often indicates ambiguous audio or model error.
Over-strict speaker verification
Setting speaker threshold too high (e.g., 0.90) rejects authorized users with legitimate speaker variations (cold, background noise). Tune threshold via ROC curves balancing false positives vs. false negatives.
✦ Key Takeaways
End-to-end voice pipelines require five stages: audio loading, spectrogram extraction, intent classification, ASR transcription, speaker identification. Each is independent and swappable.
Mel-spectrograms convert waveforms to 2D frequency-time representations suitable for CNNs. Always normalize to handle amplitude and equipment variations.
Small 2D CNNs (2 conv layers, ~50K params) efficiently classify intent from spectrograms in <100ms—suitable for edge devices.
Whisper validates intent and logs transcripts, but is too slow for primary classification. Use it to catch CNN errors and provide human-readable logs.
Speaker embeddings gate authorization. Threshold tuning balances false positives (security risk) vs. false negatives (usability). Log and review disagreements for continuous improvement.
Aisha's voice pipeline at M-Kopa achieves 94.2% accuracy, enabling secure and reliable voice control of solar systems across East Africa.